


Use:
integer_array = (img5.astype(np.float32)/255.0*65535.0-32768.0).astype(np.int16)
That will scale properly your 0,255 range (uint8) to the -32768,32767 (int16) range.
Answer from Toyo on Stack OverflowSOLVED: 3 Solutions:
-
using Numpy : np.uint16()
-
Using CTypes : ctypes.c_uint16()
-
Using Bitwise : & 0xFFFF
Hi, I'm trying to convert this code to Python from Go / C. It involves declaring a UInt16 variable and run a bit shift operation. However cant seem to create a variable with this specific type. Need some advise here.
Go Code:
package main

import "fmt"

func main() {

var dx uint16 = 38629

var dy uint16 = dx << 8

fmt.Println(dy) //58624 -> Correct value

}
Python Code:
dx = 38629

dy = (dx << 8)

print(dy) # 9889024 -> not the expected value

print(type(dx)) # <class 'int'>

print(type(dy)) # <class 'int'>
I cant seem to figure out a way to cast or similar function to get this into an Unsigned Int 16.\
Please help.
Newest 'uint16' Questions - Stack Overflow
overflow - Converting float64 array to uint16 (Python) - Stack Overflow
python - numpy array convert uin8 lsb to uint16 msb - Stack Overflow
python - Conversion of image type int16 to uint8 - Stack Overflow
All of these do different things.
np.uint8 considers only the lowest byte of your number. It's like doing value & 0xff.
>>> img = np.array([2000, -150, 11], dtype=np.int16)
>>> np.uint8(img)
array([208, 106,  11], dtype=uint8)
cv2.normalize with the cv2.NORM_MINMAX norm type normalises your values according to the normalisation function
img_new = (img - img.min()) * ((max_new - min_new) / (img.max() - img.min())) + min_new
It effectively changes one range to another and all the values in the between are scaled accordingly. By definition the original min/max values become the targetted min/max values.
>>> cv2.normalize(img, out, 0, 255, cv2.NORM_MINMAX)
array([255,   0,  19], dtype=int16)
uint8 in Matlab simply saturates your values. Everything above 255 becomes 255 and everything below 0 becomes 0.
>> uint8([2000 -150 11])

ans =

  255    0   11
If you want to replicate Matlab's functionality, you can do
>>> img[img > 255] = 255
>>> img[img < 0] = 0
Which one you want to use depends on what you're trying to do. If your int16 covers the range of your pixel values and you want to rescale those to uint8, then cv2.normalize is the answer.
the simply way to convert data format is to use the following formula. In this case it is possible to convert any array to a new custom format.
# In the case of image, or matrix/array conversion to the uint8 [0, 255]
# range

Import numpy as np

new_data = (newd_ata - np.min(new_data)) * ((255 - 0) / (np.max(new_data) -
np.new_data))) + 0
You could discard the bottom 16 bits:
n=(array_int32>>16).astype(np.int16)
which will give you this:
array([ 485, 1054, 2531], dtype=int16
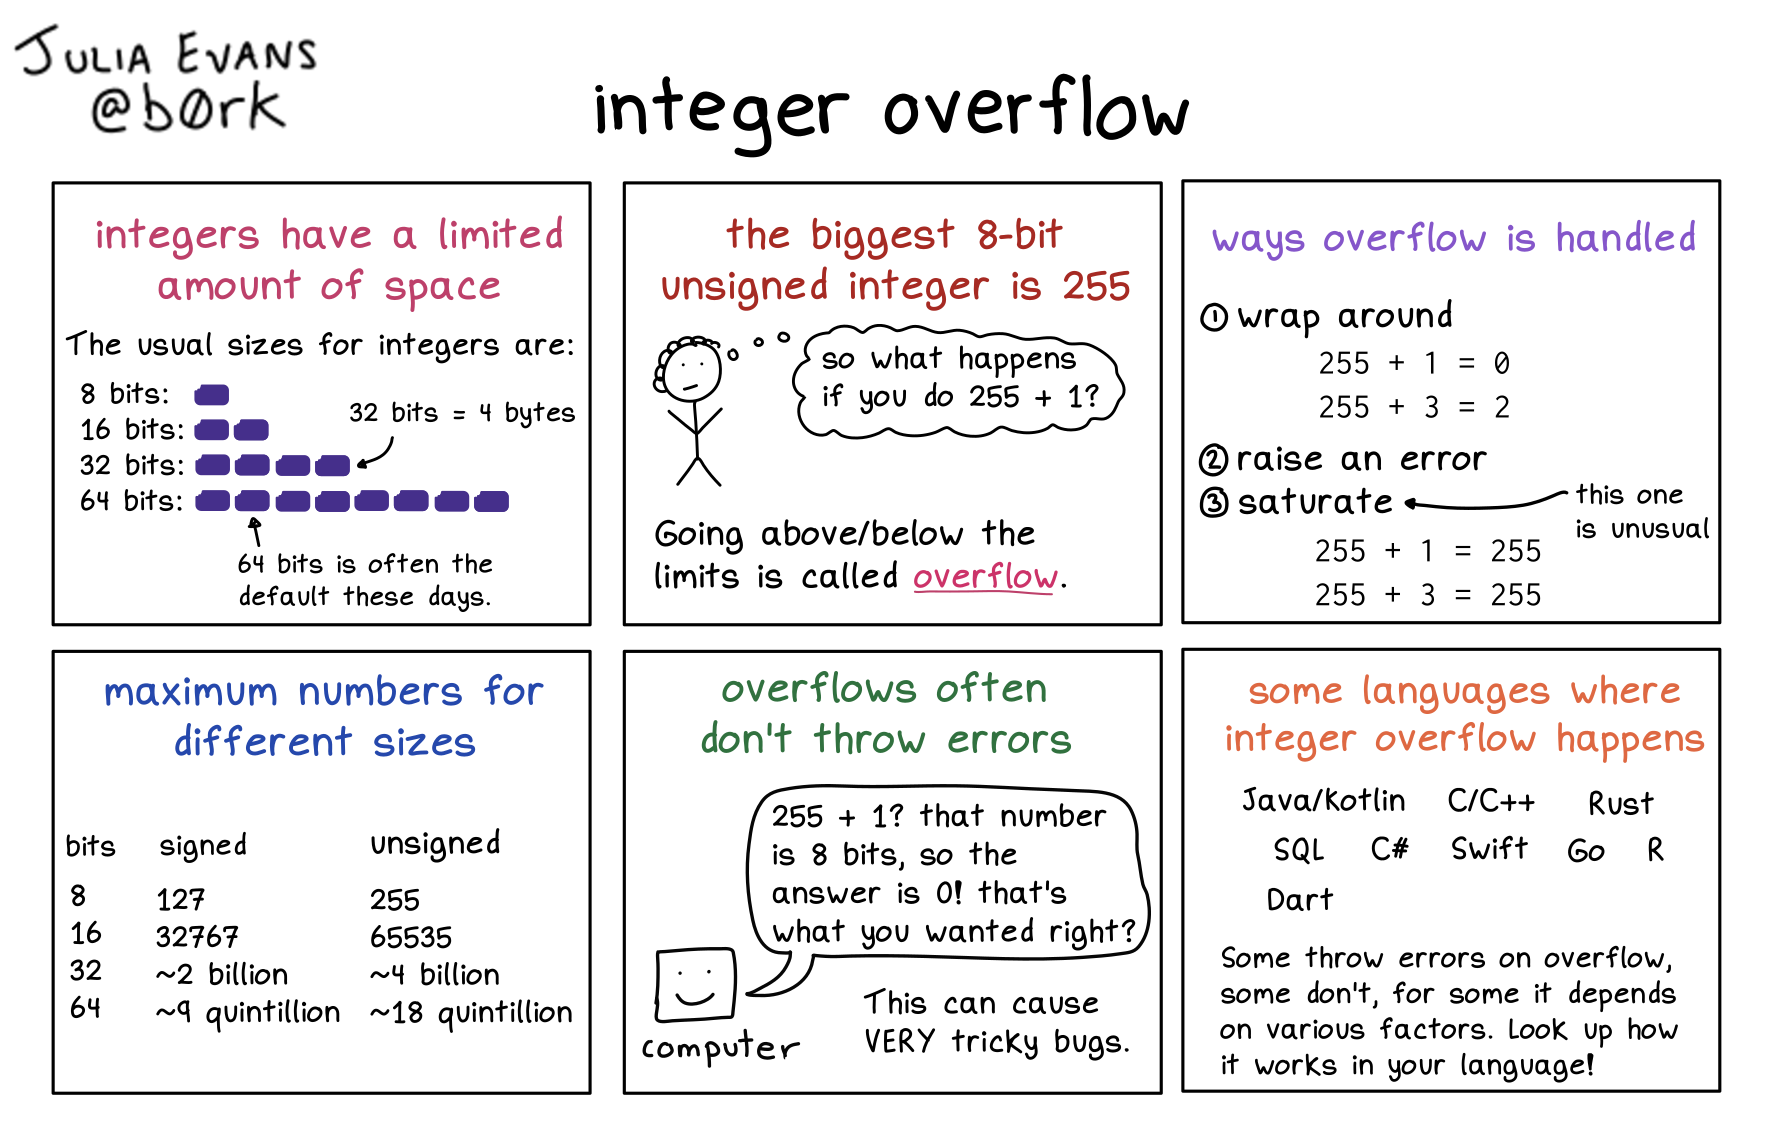
The numbers in your array_int32 are too large to be represented with 16 bits (a signed integer value with 16 bits can only represent a maximum value of 2^16-1=32767).
Apparently, numpy just sets the resulting numbers to zero in this case.
This behavior can be modified by changing the optional casting argument of astype The documentation states
Starting in NumPy 1.9, astype method now returns an error if the string dtype to cast to is not long enough in ‘safe’ casting mode to hold the max value of integer/float array that is being casted. Previously the casting was allowed even if the result was truncated.
So, an additional requirement casting='safe' will result in a TypeError, as the conversion from 32 (or 64) bits downto 16, as the maximum value of original type is too large for the new type, e.g.
import numpy as np
array_int32 = np.array([31784960, 69074944, 165871616])
array_int16 = array_int32.astype(np.int16, casting='safe')
results in
TypeError: Cannot cast array from dtype('int64') to dtype('int16') according to the rule 'safe'
It seems that numpy cannot "safely" cast uint into int while using union1d operation. Is there a particular reason why? While i understand why you cannot cast float to int in a safe way, or int to uint, the reason for not being able to cast from uint to int is nebulous to me.
a = np.array([0,1,2,3],dtype='uint')
b = np.array([4,5,6],dtype='int')
c = np.union1d(a,b)
print(c.dtype)
The above example prints float64. Also, the following line returns False :
np.can_cast('uint','int')The next example can cast without trouble :
np.array(np.array([0,1,2],dtype='uint'),dtype='int')
NumPy functions are designed to have consistent return dtypes, based only on the dtypes of their arguments. This is an essential feature for avoiding bugs based on strange input values, and lets you accelerate numpy functions with tools like Numba.
Not every signed int can be safely cast into a unsigned int of the same size (e.g., 2 ** 63 is a valid 64-bit unsigned int but not a valid signed int). Likewise, not every signed int can be cast into an unsigned int (consider negative numbers). Hence, NumPy uses the next largest size dtype that can hold both values. 64-bits are the largest size integers supported by numpy, so it uses float64 instead. In contrast, as shown in the other comment, uint16 + int16 can fit in int32.
In contrast, np.arraycoerces dtypes of input arrays. This means it always succeeds.... even if the values cannot be safely represented:
In [31]: np.array(np.arange(2 ** 40, 2 ** 40 + 3), dtype=np.int16)
Out[31]: array([0, 1, 2], dtype=int16)
np.uint16 covers the numbers 0 to 65535, while np.int16 covers the numbers −32768 to 32767. Note that they can both represent numbers that the other cannot; the unsigned version cannot represent negative numbers and the signed version cannot represent "high" positive numbers. You need to promote to a higher size if you want to merge them. The same is true of the two kinds of 32-bit integers and any other size of integer you care to use.
Use ctypes.c_ushort:
>>> import ctypes
>>> word.insert(0, ctypes.c_ushort(0x19c6acc6).value)
>>> word
array('H', [44230])
If NumPy is available then:
>>> numpy.ushort(0x19c6acc6)
44230
The classical way is to extract the relevant bits using a mask:
>>> hex(0x19c6acc6 & 0xffff)
'0xacc6'
You need to use shorts or unsigned shorts:)
>>> import struct
>>> data_read
b'\x00\x00\x01\x00\x02\x00\x03\x00'
>>> struct.unpack("hhhh" , data_read)
(0, 1, 2, 3)
>>> struct.unpack("HHHH" , data_read)
(0, 1, 2, 3)
If you get the ascii display for b,',\,x, etc., it means that the file actually contains it. In fact it is caused by the str(b_a) call.
Demo:
>>> b_a = b'\x00\x00\x01\x00\x02\x00\x03\x00'
>>> s_a = str(b_a)
>>> print(s_a)
b'\x00\x00\x01\x00\x02\x00\x03\x00'
>>> [hex(ord(x)) for x in s_a]
['0x62', '0x27', '0x5c', '0x78', '0x30', '0x30', '0x5c', '0x78', '0x30', '0x30', '0x5c', '0x78', '0x30', '0x31', '0x5c', '0x78', '0x30', '0x30', '0x5c', '0x78', '0x30', '0x32', '0x5c', '0x78', '0x30', '0x30', '0x5c', '0x78', '0x30', '0x33', '0x5c', '0x78', '0x30', '0x30', '0x27']
which is the display for b, ', \, x, 0, etc.
ast.literal_eval can be used to convert it back to a byte string. Demo:
>>> b2 = ast.literal_eval(s_a)
>>> b2 == b_a
True
>>> struct.unpack('HHHH', b2)
(0, 1, 2, 3)
So if you want to keep the str call when writing, you have to read it that way:
with open('data_0.txt') as f:
    data_read = f.read()
data = struct.unpack('HHHH', ast.literal_eval(data_read))
You can use cv2.convertScaleAbs for this problem. See the Documentation.
Check out the command terminal demo below :
>>> img = np.empty((100,100,1),dtype = np.uint16)
>>> image = cv2.cvtColor(img,cv2.COLOR_GRAY2BGR)

>>> cvuint8 = cv2.convertScaleAbs(image)

>>> cvuint8.dtype
dtype('uint8')
Hope it helps!!!
I suggest you to use this :
outputImg8U = cv2.convertScaleAbs(inputImg16U, alpha=(255.0/65535.0))
this will output a uint8 image & assign value between 0-255 with respect to there previous value between 0-65535
exemple :
pixel with value == 65535 will output with value 255
pixel with value == 1300 will output with value 5 etc...