


There's no need to manually set the colors. Instead, specify a grayscale colormap...
import numpy as np
import matplotlib.pyplot as plt

# Generate data...
x = np.random.random(10)
y = np.random.random(10)

# Plot...
plt.scatter(x, y, c=y, s=500) # s is a size of marker
plt.gray()

plt.show()

Or, if you'd prefer a wider range of colormaps, you can also specify the cmap kwarg to scatter. To use the reversed version of any of these, just specify the "_r" version of any of them. E.g. gray_r instead of gray. There are several different grayscale colormaps pre-made (e.g. gray, gist_yarg, binary, etc).
import matplotlib.pyplot as plt
import numpy as np

# Generate data...
x = np.random.random(10)
y = np.random.random(10)

plt.scatter(x, y, c=y, s=500, cmap='gray')
plt.show()
python - How to color scatter markers as a function of a third variable - Stack Overflow
Change colour of curve according to its y-value in matplotlib
python - How to change data points color based on some variable - Stack Overflow
How to color different segments of plotted curve based on value?
There's no need to manually set the colors. Instead, specify a grayscale colormap...
import numpy as np
import matplotlib.pyplot as plt

# Generate data...
x = np.random.random(10)
y = np.random.random(10)

# Plot...
plt.scatter(x, y, c=y, s=500) # s is a size of marker
plt.gray()

plt.show()
Or, if you'd prefer a wider range of colormaps, you can also specify the cmap kwarg to scatter. To use the reversed version of any of these, just specify the "_r" version of any of them. E.g. gray_r instead of gray. There are several different grayscale colormaps pre-made (e.g. gray, gist_yarg, binary, etc).
import matplotlib.pyplot as plt
import numpy as np

# Generate data...
x = np.random.random(10)
y = np.random.random(10)

plt.scatter(x, y, c=y, s=500, cmap='gray')
plt.show()
In matplotlib grey colors can be given as a string of a numerical value between 0-1.
For example c = '0.1'
Then you can convert your third variable in a value inside this range and to use it to color your points.
In the following example I used the y position of the point as the value that determines the color:
from matplotlib import pyplot as plt

x = [1, 2, 3, 4, 5, 6, 7, 8, 9]
y = [125, 32, 54, 253, 67, 87, 233, 56, 67]

color = [str(item/255.) for item in y]

plt.scatter(x, y, s=500, c=color)

plt.show()

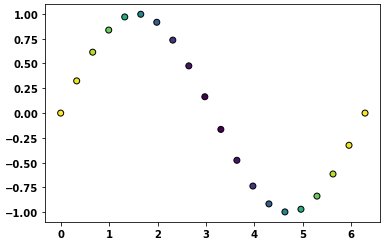
This is what matplotlib.pyplot.scatter is for.
If no colormap is specified, scatter will use whatever the default colormap is set to. To specify which colormap scatter should use, use the cmap kwarg (e.g. cmap="jet").
As a quick example:
import matplotlib.pyplot as plt
import matplotlib.colors as mcolors
import numpy as np

# Generate data...
t = np.linspace(0, 2 * np.pi, 20)
x = np.sin(t)
y = np.cos(t)

plt.scatter(t, x, c=y, ec='k')
plt.show()
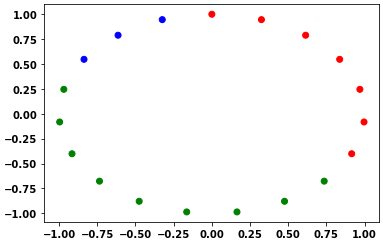
One may specify a custom color map and norm
cmap, norm = mcolors.from_levels_and_colors([0, 2, 5, 6], ['red', 'green', 'blue'])
plt.scatter(x, y, c=t, cmap=cmap, norm=norm)
If you want to plot lines instead of points, see this example, modified here to plot good/bad points representing a function as a black/red as appropriate:
def plot(xx, yy, good):
    """Plot data

    Good parts are plotted as black, bad parts as red.

    Parameters
    ----------
    xx, yy : 1D arrays
        Data to plot.
    good : `numpy.ndarray`, boolean
        Boolean array indicating if point is good.
    """
    import numpy as np
    import matplotlib.pyplot as plt
    fig, ax = plt.subplots()
    from matplotlib.colors import from_levels_and_colors
    from matplotlib.collections import LineCollection
    cmap, norm = from_levels_and_colors([0.0, 0.5, 1.5], ['red', 'black'])
    points = np.array([xx, yy]).T.reshape(-1, 1, 2)
    segments = np.concatenate([points[:-1], points[1:]], axis=1)
    lines = LineCollection(segments, cmap=cmap, norm=norm)
    lines.set_array(good.astype(int))
    ax.add_collection(lines)
    plt.show()
Hello, so I am trying to figure out how to plot a dataframe column where the color of the line changes based on its value, but I am stuck on how to get these values referenced.
For example, I have this dataframe:
    Timestamp    Value
-------------------------
0       5:00         4
1       5:01         5
2       5:02         8
3       5:03        12
4       5:04        13
5       5:05         2
...
I simple run some form of:
df.plot(x="Timestamp", y=["Value"], figsize=(9, 8))
to get a plot of the values changing over time.
Now, I have my values separated into different categories/bins where 0-5 = "Low", 6-15 = "Mid" and 16+ = "High". I want to have my same plot, but now with all values on the curve corresponding to "Low" to be blue, corresponding to "Mid" to be green, and corresponding to "High" to be red. So I will see see a single curve plotted, made up from the "Value" column, but segmented into different colors based on value. How can I accomplish this in python? I am confused about how to set up an index/key for translating values to colors and what argument is needed in .plot() to actually have color based on value. I would appreciate any help with this, thanks!


You could look into using a qualitative colormap from https://matplotlib.org/tutorials/colors/colormaps.html instead of one based on a gradient. They might fit your type of data more effectively.
Looking something like

Your values range from -1..10 which spans 12 integer values. So you should use a color map that has 12 colors in it, such as cmap='Paired'. And also be sure to specify vmin=-1 and vmax=10. In case you want to create a custom color map, you can use cmap=mymap in which...
    mymap = matplotlib.colors.ListedColormap([
        '#FFFF00', # -1
        '#FF00FF', # 0
        '#00FFFF', # +1
        'none', 'none', 'none', 'none', 'none', 'none', 'none', 'none',
        '#00FF00', # +10
        ])