


To assign a column, you can create a rolling object based on your Series:
df['new_col'] = data['column'].rolling(5).mean()
The answer posted by ac2001 is not the most performant way of doing this. He is calculating a rolling mean on every column in the dataframe, then he is assigning the "ma" column using the "pop" column. The first method of the following is much more efficient:
%timeit df['ma'] = data['pop'].rolling(5).mean()
%timeit df['ma_2'] = data.rolling(5).mean()['pop']

1000 loops, best of 3: 497 µs per loop
100 loops, best of 3: 2.6 ms per loop
I would not recommend using the second method unless you need to store computed rolling means on all other columns.
Answer from Andrew L on Stack OverflowTo assign a column, you can create a rolling object based on your Series:
df['new_col'] = data['column'].rolling(5).mean()
The answer posted by ac2001 is not the most performant way of doing this. He is calculating a rolling mean on every column in the dataframe, then he is assigning the "ma" column using the "pop" column. The first method of the following is much more efficient:
%timeit df['ma'] = data['pop'].rolling(5).mean()
%timeit df['ma_2'] = data.rolling(5).mean()['pop']

1000 loops, best of 3: 497 µs per loop
100 loops, best of 3: 2.6 ms per loop
I would not recommend using the second method unless you need to store computed rolling means on all other columns.
Edit: pd.rolling_mean is deprecated in pandas and will be removed in future. Instead: Using pd.rolling you can do:
df['MA'] = df['pop'].rolling(window=5,center=False).mean()
for a dataframe df:
          Date    stock  pop
0   2016-01-04  325.316   82
1   2016-01-11  320.036   83
2   2016-01-18  299.169   79
3   2016-01-25  296.579   84
4   2016-02-01  295.334   82
5   2016-02-08  309.777   81
6   2016-02-15  317.397   75
7   2016-02-22  328.005   80
8   2016-02-29  315.504   81
9   2016-03-07  328.802   81
To get:
          Date    stock  pop    MA
0   2016-01-04  325.316   82   NaN
1   2016-01-11  320.036   83   NaN
2   2016-01-18  299.169   79   NaN
3   2016-01-25  296.579   84   NaN
4   2016-02-01  295.334   82  82.0
5   2016-02-08  309.777   81  81.8
6   2016-02-15  317.397   75  80.2
7   2016-02-22  328.005   80  80.4
8   2016-02-29  315.504   81  79.8
9   2016-03-07  328.802   81  79.6
Documentation: http://pandas.pydata.org/pandas-docs/stable/generated/pandas.DataFrame.rolling.html
Old: Although it is deprecated you can use:
df['MA']=pd.rolling_mean(df['pop'], window=5)
to get:
          Date    stock  pop    MA
0   2016-01-04  325.316   82   NaN
1   2016-01-11  320.036   83   NaN
2   2016-01-18  299.169   79   NaN
3   2016-01-25  296.579   84   NaN
4   2016-02-01  295.334   82  82.0
5   2016-02-08  309.777   81  81.8
6   2016-02-15  317.397   75  80.2
7   2016-02-22  328.005   80  80.4
8   2016-02-29  315.504   81  79.8
9   2016-03-07  328.802   81  79.6
Documentation: http://pandas.pydata.org/pandas-docs/version/0.17.0/generated/pandas.rolling_mean.html
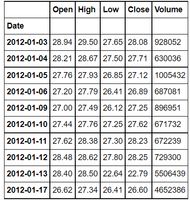
In the meantime, a time-window capability was added. See this link.
In [1]: df = DataFrame({'B': range(5)})

In [2]: df.index = [Timestamp('20130101 09:00:00'),
   ...:             Timestamp('20130101 09:00:02'),
   ...:             Timestamp('20130101 09:00:03'),
   ...:             Timestamp('20130101 09:00:05'),
   ...:             Timestamp('20130101 09:00:06')]

In [3]: df
Out[3]:
                     B
2013-01-01 09:00:00  0
2013-01-01 09:00:02  1
2013-01-01 09:00:03  2
2013-01-01 09:00:05  3
2013-01-01 09:00:06  4

In [4]: df.rolling(2, min_periods=1).sum()
Out[4]:
                       B
2013-01-01 09:00:00  0.0
2013-01-01 09:00:02  1.0
2013-01-01 09:00:03  3.0
2013-01-01 09:00:05  5.0
2013-01-01 09:00:06  7.0

In [5]: df.rolling('2s', min_periods=1).sum()
Out[5]:
                       B
2013-01-01 09:00:00  0.0
2013-01-01 09:00:02  1.0
2013-01-01 09:00:03  3.0
2013-01-01 09:00:05  3.0
2013-01-01 09:00:06  7.0
What about something like this:
First resample the data frame into 1D intervals. This takes the mean of the values for all duplicate days. Use the fill_method option to fill in missing date values. Next, pass the resampled frame into pd.rolling_mean with a window of 3 and min_periods=1 :
pd.rolling_mean(df.resample("1D", fill_method="ffill"), window=3, min_periods=1)

            favorable  unfavorable     other
enddate
2012-10-25   0.495000     0.485000  0.025000
2012-10-26   0.527500     0.442500  0.032500
2012-10-27   0.521667     0.451667  0.028333
2012-10-28   0.515833     0.450000  0.035833
2012-10-29   0.488333     0.476667  0.038333
2012-10-30   0.495000     0.470000  0.038333
2012-10-31   0.512500     0.460000  0.029167
2012-11-01   0.516667     0.456667  0.026667
2012-11-02   0.503333     0.463333  0.033333
2012-11-03   0.490000     0.463333  0.046667
2012-11-04   0.494000     0.456000  0.043333
2012-11-05   0.500667     0.452667  0.036667
2012-11-06   0.507333     0.456000  0.023333
2012-11-07   0.510000     0.443333  0.013333
UPDATE: As Ben points out in the comments, with pandas 0.18.0 the syntax has changed. With the new syntax this would be:
df.resample("1d").sum().fillna(0).rolling(window=3, min_periods=1).mean()